Artificial intelligence running on a classic Super Nintendo console
Por Arthur Bittencourt ·
Local execution of artificial intelligence on retro hardware
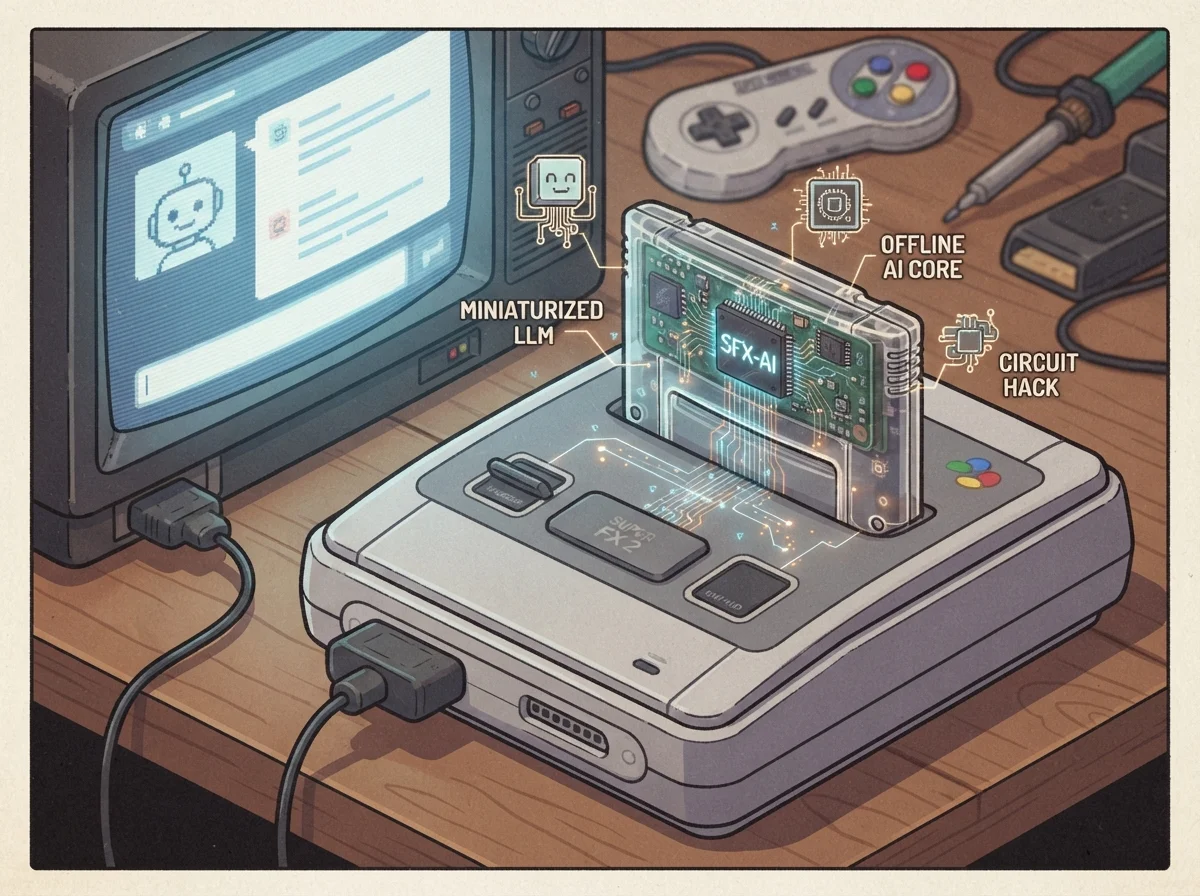
Developer Benj Edwards, creator of the Vintage Computing platform, demonstrated that it is possible to run a functional language model directly on the Super Nintendo (SNES) hardware, without needing any internet connection or external servers. The project uses the Super FX 2 coprocessor to process the interactions of a chatbot inspired by ChatGPT, allowing the 1990 video game to act as an autonomous conversation terminal.
This discovery is relevant because it illustrates the extreme limits of language model compression and the viability of "edge" technologies, where processing occurs right at the edge, on the user's final device. In a scenario where most people rely on large data centers to access AI tools, this experiment proves that even obsolete electronic components possess sufficient computational capacity if the software is adequately optimized to handle severe memory and clock speed restrictions.
The technical architecture behind the offline chat
To make this possible, the Super FX 2 chip was used, a component originally developed by Silicon Graphics to assist the console in complex mathematical tasks, such as basic 3D rendering. It operates at a frequency of 21.47 MHz, which requires an extremely lean artificial intelligence model. Edwards used a small language model composed of only 2.2 million parameters—understand "parameters" as the artificial neural connections that determine how the machine responds; imagine them as small tuning knobs that define the tone and direction of a sentence.
The training of this specific model was based on conversations generated by OpenAI's gpt-oss-120b. However, due to the limitation of the old hardware, the scale is drastically reduced: while modern models operate with billions or trillions of parameters, this version needs to be thousands of times smaller to fit in the system. The result of this compression allows it to generate approximately two units of text per second, a slow speed compared to current standards, but technically significant given the historical context of the processor involved.
User experience and available versions
Currently, the experiment can be tested using a web emulator utilizing Snes9x, where users interact via keyboard. There are two levels of complexity for this project: a basic 4 MB version, which contains purely the language model logic, and an expanded 19 MB version. This second option integrates information extracted from about 150 thousand Wikipedia articles adapted into simplified English, allowing the AI access to a larger volume of facts before formulating responses to the user.
For those who own the original physical console, the software can also be run via flash cartridges compatible with the Super FX 2 chip, and in the expanded version, with the MSU-1 chip, which assists in managing additional memory. The interface maintains the characteristic retro aesthetic of the 1990s, including classic sound effects and chiptune music tracks (music specifically composed by old console sound chips), unifying the visual and auditory experience with the new technological functionality.
System limitations and comparison with modern models
It is important to note that this implementation does not replace the capabilities of modern versions of ChatGPT or Gemini. Due to having few parameters, the chatbot tends to offer very simple responses and frequently produces nonsensical or incoherent statements because of the lack of computational "mental space" to process complex nuances. Unlike current systems that analyze vast contexts simultaneously, this model operates more like a highly sophisticated autocomplete feature than an intelligent assistant capable of solving multifaceted problems.
Compared to current standards, where models are run on powerful GPUs capable of managing billions of operations per second, the SNES version is an engineering exercise focused on radical miniaturization. It serves less as a practical productivity tool and more as a proof of concept regarding the modularity of artificial intelligence. The experiment demonstrates that, if we sacrifice precision and speed, we can port basic cognitive functions to any hardware that has minimum logical processing capacity.
Future prospects for AI on limited devices
In the long run, this kind of development signals a growing trend toward privacy and efficiency: running local AIs on small electronic devices without needing the cloud. As quantization techniques (the process of reducing the numerical precision of neural networks to save memory) evolve, we might see functional versions of assistants integrated into appliances or older wearables, operating completely offline. For now, Ben Edwards' project remains a fascinating technical curiosity and a lesson in extreme optimization.